7
7
10
1
2
0
8
9
7
9Randomness
Jon Reades - j.reades@ucl.ac.uk
1st October 2026
Many things are surprisingly non-random…
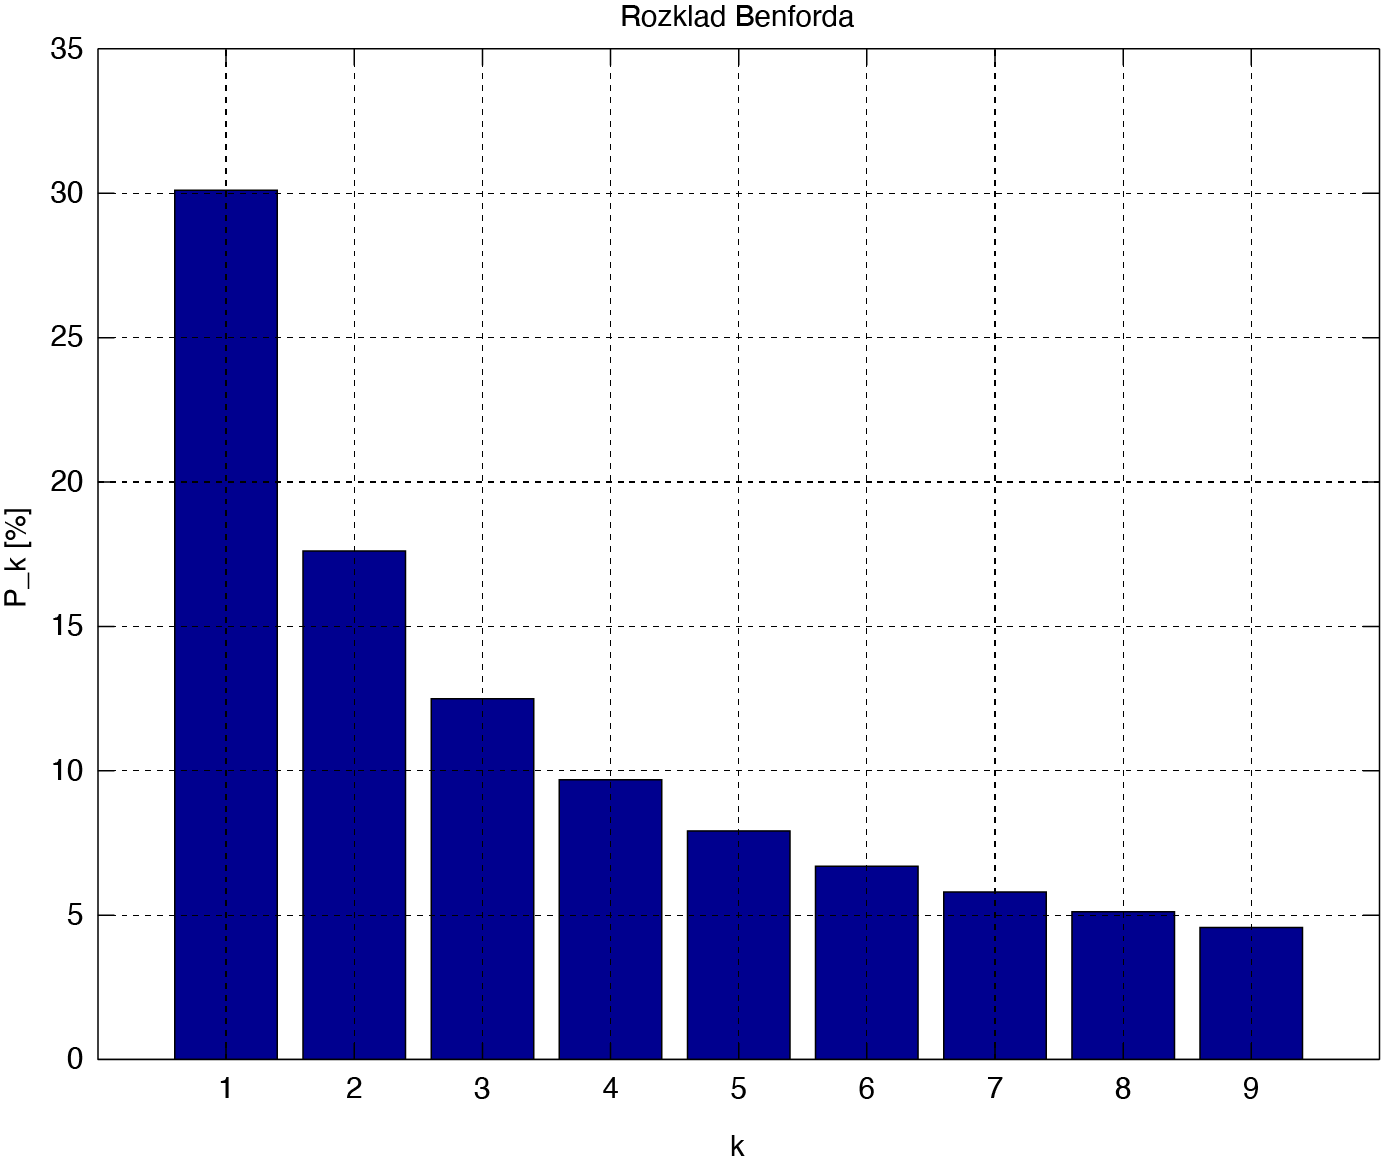
Benford’s Law, which has applications in data science and fraud detection.
Reproducibility: Good or Bad?
Depends on the problem:
- Banking and encryption?
- Sampling and testing?
- Reproducing research/documentation?
Not Very Good Encryption
| Cyphertext | Output |
|---|---|
| ROT0 | To be or not to be, That is the question |
| ROT1 | Up cf ps opu up cf, Uibu jt uif rvftujpo |
| ROT2 | Vq dg qt pqv vq dg, Vjcv ku vjg swguvkqp |
| … | … |
| ROT9 | Cx kn xa wxc cx kn, Cqjc rb cqn zdnbcrxw |
ROT is known as the Caesar Cypher, but since the transformation is simple (A..Z+=x) decryption is easy now. How can we make this harder?
Python is Random
See also: random.randrange, random.choice, random.sample, random.random, random.gauss, etc.
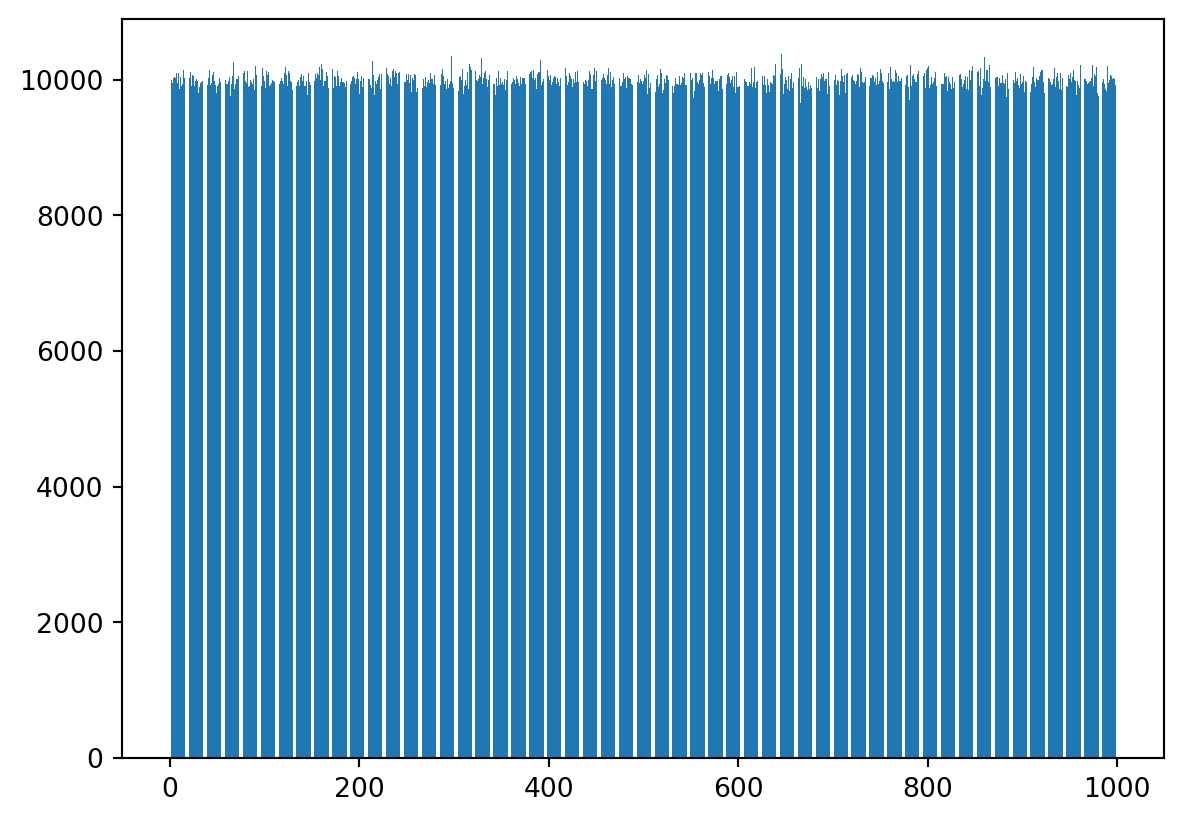
And Repeat…
0 -> 10110
1 -> 9911
2 -> 9917
3 -> 9982
4 -> 10036
5 -> 9849
6 -> 10275
7 -> 10059
8 -> 9767
9 -> 10094Aaaaaaaaaaand Repeat
Answer on next slide…
Aaaaaaaaaaand Repeat
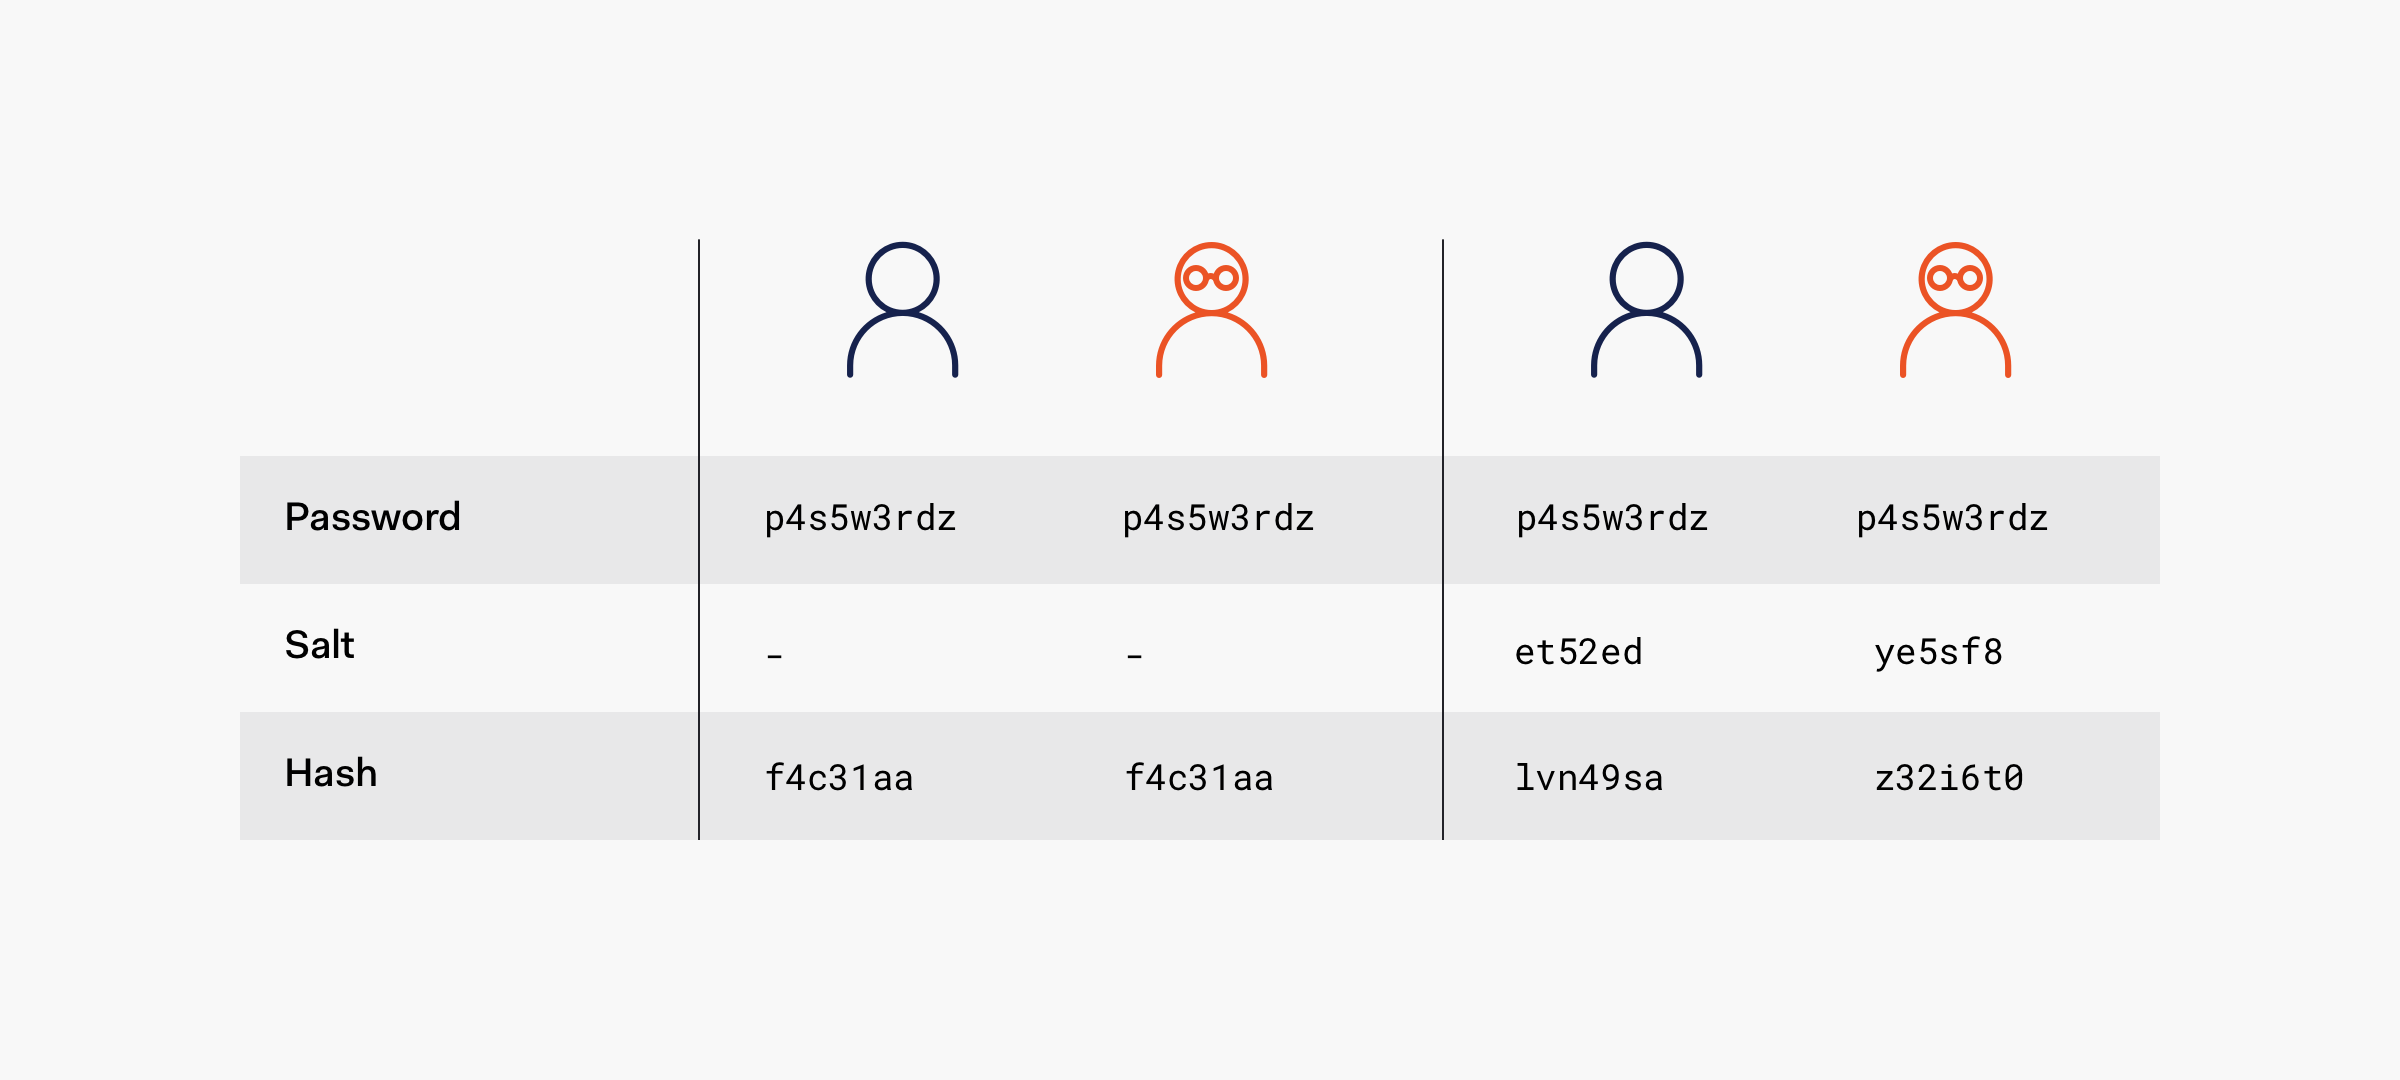
Seeds and Salts
Computers are pseudo-random number generators. Seeds and salts ensure different outputs from the same inputs.1
Just add salt
Hashing
Spot the difference:
import hashlib # Can take a 'salt' (similar to a 'seed')

r1 = hashlib.md5('CASA Intro to Programming'.encode())
print(f"The hashed equivalent of r1 is: {r1.hexdigest()}")

r2 = hashlib.md5('CASA Intro to Programming '.encode())
print(f"The hashed equivalent of r2 is: {r2.hexdigest()}")

r3 = hashlib.md5('CASA Intro to Programming'.encode())
print(f"The hashed equivalent of r3 is: {r3.hexdigest()}")
The hashed equivalent of r1 is: acd601db5552408851070043947683ef
The hashed equivalent of r2 is: 4458e89e9eb806f1ac60acfdf45d85b6
The hashed equivalent of r3 is: acd601db5552408851070043947683efAnd Note…
The text is 'Midsummer Night's Dream'
The text is 120,008 characters long
This can be hashed into: 8645f1222097ad5c953b3a82b536ec22JupyterLab Password
To set a password in JupyterLab you need something like this:
How this was generated:
import uuid, hashlib
salt = uuid.uuid4().hex[:16] # Truncate salt
password = 'casa2021'        # Set password

# Here we combine the password and salt to
# 'add complexity' to the hash
hashed_password = hashlib.sha1(password.encode() +
                  salt.encode()).hexdigest()
print(':'.join(['sha1',salt,hashed_password]))sha1:4755b84bad7c4b50:0506faf1cabdfcae20378bde18cd3a0806431bb4Encryption & Security
Simple hashing algorithms are not normally secure enough for operational use. Genuine security training takes a whole degree + years of experience.
Areas to look at for more secure computing:
- Public and Private Key Encryption (esp. OpenSSL)
- Privileges used by Applications (esp. Podman vs Docker)
- Revocable Tokens (e.g. for APIs)
- Injection Attacks (esp. for SQL using NULL-byte and similar)
Back to Randomness
Two main libraries where seeds are set:
How Seeds Work
flowchart LR
    accTitle: Mermaid chart explaining how seeds work
    accDescr: seed(42) starts a fixed sequence of numbers (17, 9, 7, 4 and so on). getstate() saves the position after 9, and setstate() returns to that saved position so the same numbers are drawn again.
    SEED("seed(42)")

    subgraph TAPE [Sequence]
        N1["17"] --> N2["9"] --> N4["7"] --> N5["4"] --> NN["..."]
    end

    subgraph TAPEX [Sequence]
        NN1["17"] .- NN2["9"] --> NN4["7"] --> NN5["4"] --> NNN["..."]
    end

    SEED --> N1

    N2-. "getstate()" .->SNAP("Saved State")
    SNAP-. "setstate()" .->NN2

    style TAPE fill: lightpink
    style TAPEX fill: lightpink
Seeds and State
Repetition 0:
    [10, 1, 0, 4, 3, 3, 2, 1, 10, 8]
Repetition 1:
    [10, 1, 0, 4, 3, 3, 2, 1, 10, 8]
Repetition 2:
    [10, 1, 0, 4, 3, 3, 2, 1, 10, 8]
Question!
Where would you use a mix of randomness and reproducbility as part of a data analysis process?
